GPT-6.1 Terra on the quick suite
OpenAI released GPT-6.1 Terra on 26 October. I ran it in Codex CLI the same day, beside Claude Opus 5.5, Claude Sonnet 5.5, GPT-6.1 Sol and GPT-6 Luna.
Speed#
Time to finish
Seconds from starting the tool to its exit, one short explain task. Lower is better.
Claude Opus 5.5, Claude Sonnet 5.5 and GPT-6 Luna took turns in the same batch: a median run of 16.6 s, 9.7 s and 5.1 s. GPT-6 Luna's runs overlap Terra's. Every run is in the race and the table.
Every run, one row each
| Model | Tool | Run 1 | Run 2 | Run 3 | Run 4 | Run 5 | Run 6 |
|---|---|---|---|---|---|---|---|
| GPT-6.1 Terra | Codex CLI | 6.5 s | 5.7 s | 5.1 s | 5.6 s | 5.6 s | 5.0 s |
| Claude Opus 5.5 | Claude Code | 16.8 s | 18.1 s | 12.2 s | 14.2 s | 16.3 s | 18.8 s |
| Claude Sonnet 5.5 | Claude Code | 11.2 s | 24.0 s | 9.4 s | 8.2 s | 7.6 s | 10.1 s |
| GPT-6.1 Sol | Codex CLI | 9.3 s | 11.9 s | 11.5 s | 10.3 s | 10.0 s | 10.8 s |
| GPT-6 Luna | Codex CLI | 5.5 s | 5.5 s | 5.0 s | 5.1 s | 4.9 s | 5.0 s |
The table scrolls sideways on a small screen.
A batch is one set of runs made together.
Source: WorkloadBench at workloadbench.brenhq.com, updated 26 October 2026. 30 runs, six per model, medium effort, each in its own tool.
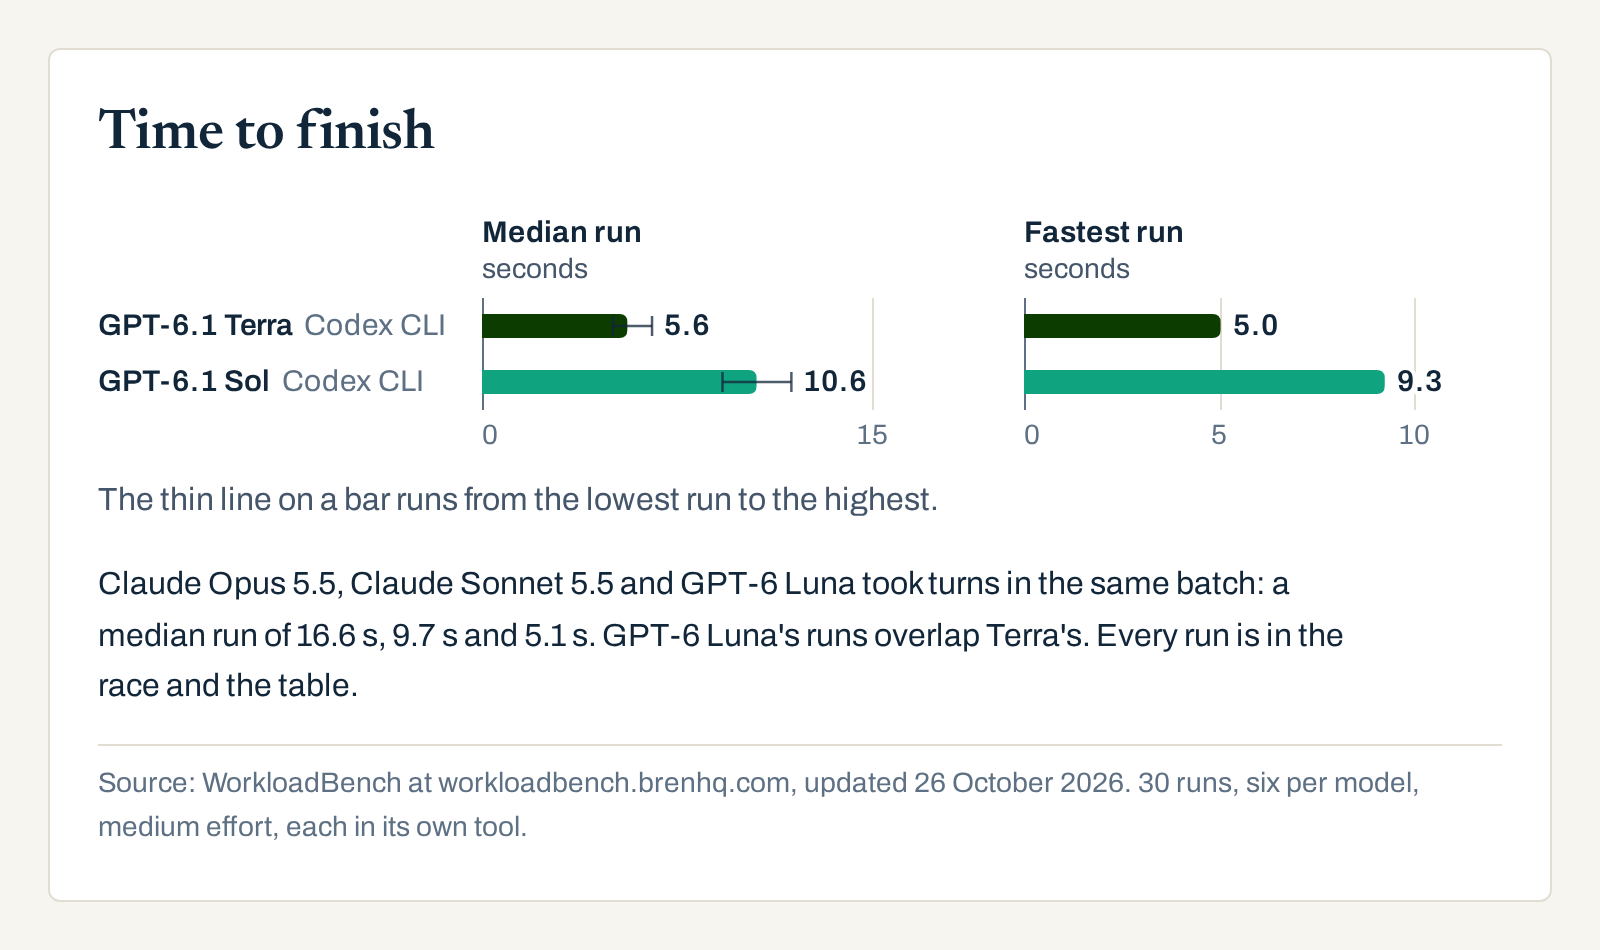
- GPT-6.1 Terra: 5.0 to 6.5 s
- Claude Opus 5.5: 12.2 to 18.8 s
- Claude Sonnet 5.5: 7.6 to 24.0 s
- GPT-6.1 Sol: 9.3 to 11.9 s
- GPT-6 Luna: 4.9 to 5.5 s
Output speed#
Output speed
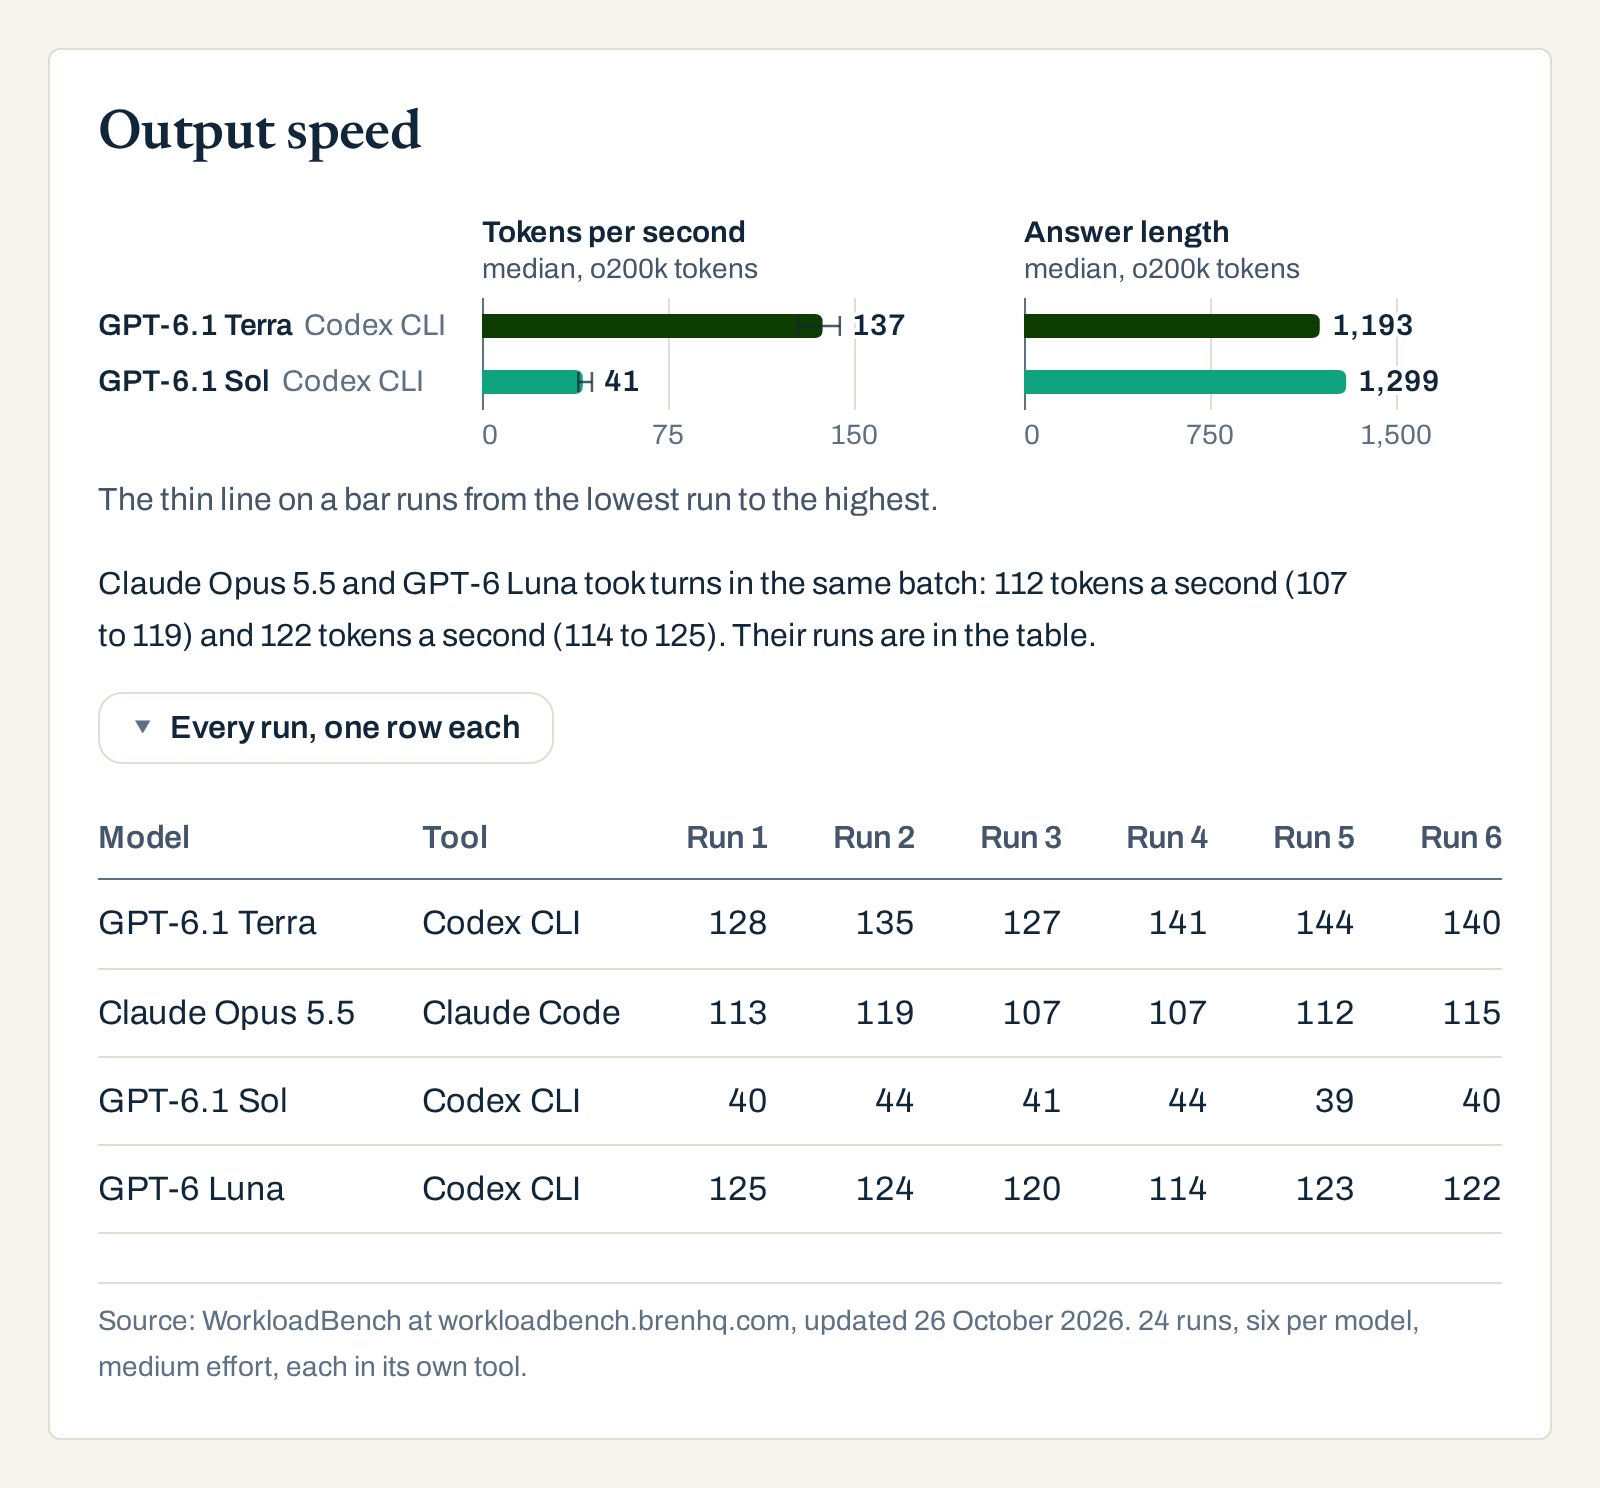
Tokens per second while each answer streamed, a walkthrough of at least 600 words. Higher is better.
Claude Opus 5.5 and GPT-6 Luna took turns in the same batch: 112 tokens a second (107 to 119) and 122 tokens a second (114 to 125). Their runs are in the table.
Every run, one row each
| Model | Tool | Run 1 | Run 2 | Run 3 | Run 4 | Run 5 | Run 6 |
|---|---|---|---|---|---|---|---|
| GPT-6.1 Terra | Codex CLI | 128 | 135 | 127 | 141 | 144 | 140 |
| Claude Opus 5.5 | Claude Code | 113 | 119 | 107 | 107 | 112 | 115 |
| GPT-6.1 Sol | Codex CLI | 40 | 44 | 41 | 44 | 39 | 40 |
| GPT-6 Luna | Codex CLI | 125 | 124 | 120 | 114 | 123 | 122 |
Tokens per second, o200k tokens over the seconds from the answer's first text to its last.
The table scrolls sideways on a small screen.
Source: WorkloadBench at workloadbench.brenhq.com, updated 26 October 2026. 24 runs, six per model, medium effort, each in its own tool.
Cost#
Cost per run
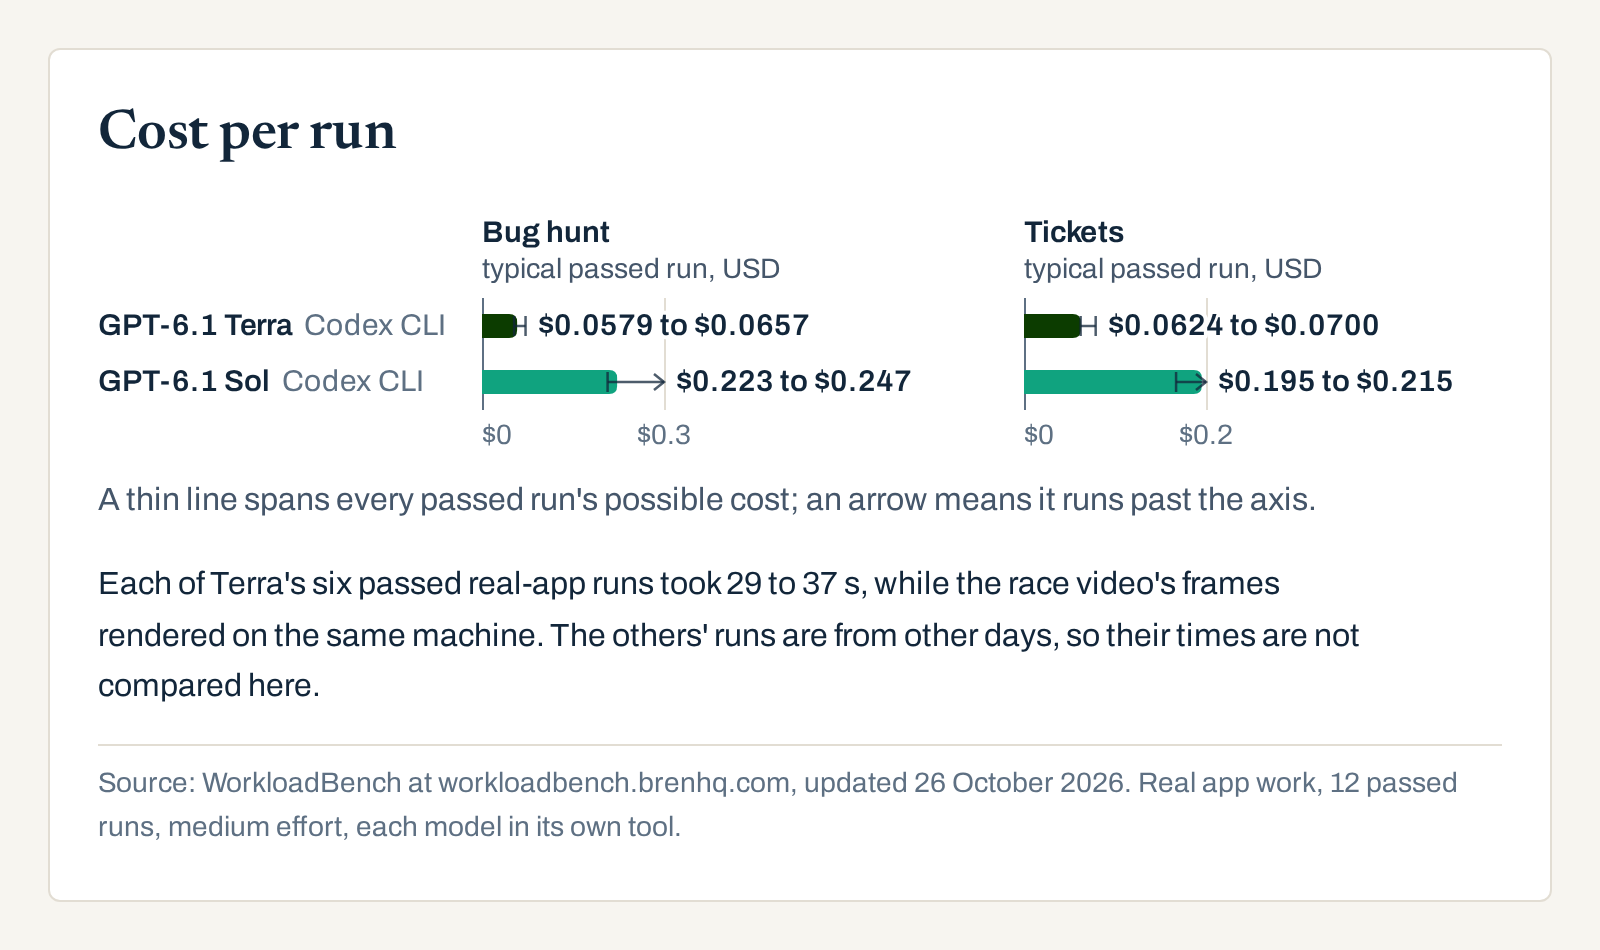
Real app work, the typical passed run at list prices when run. GPT-6.1 Terra and GPT-6.1 Sol fixed all 20 bugs and passed all 17 ticket tests in every run. Lower is cheaper.
Each of Terra's six passed real-app runs took 29 to 37 s, while the race video's frames rendered on the same machine. The others' runs are from other days, so their times are not compared here.
Typical means the middle run, or the midpoint of the two middle runs.
Source: WorkloadBench at workloadbench.brenhq.com, updated 26 October 2026. Real app work, 12 passed runs, medium effort, each model in its own tool.
Notes
GPT costs are a range because Codex logs 0 cache writes on every run: from OpenAI's input rate to its cache-write rate for the prompt tokens not read from cache.
Claude Opus 5.5, Claude Sonnet 5.5 and GPT-6 Luna's costs on the same tests are in the table below.
Every check#
The same real app work for all five.
Hidden tests are tests the model never sees. A run passes its gate when every test passes, its own new ones included, and no existing test file was changed, renamed or deleted; new test files are fine.
| Check | GPT-6.1 Terra | Claude Opus 5.5 | Claude Sonnet 5.5 | GPT-6.1 Sol | GPT-6 Luna |
|---|---|---|---|---|---|
| Bug hunt: bugs fixed of 20, each run | 20, 20, 20 of 20 | 20, 20, 20 of 20 | 19, 19, 19 of 20 | 20, 20, 20 of 20 | 19, 18, 17 of 20 |
| Bug hunt: runs that failed the gate | 0 of 3 | 0 of 3 | 0 of 3 | 0 of 3 | 0 of 3 |
| Bug hunt: estimated cost per run at list prices when run, median | $0.0579 to $0.0657 | $0.783 | $0.151 | $0.223 to $0.247 | $0.00720 to $0.00811 |
| Tickets: hidden tests passed, each run | 17, 17, 17 of 17 | 17, 17, 17 of 17 | 17, 17, 17 of 17 | 17, 17, 17 of 17 | 17, 17, 15 of 17 |
| Tickets: runs that failed the gate | 0 of 3 | 0 of 3 | 0 of 3 | 0 of 3 | 1 of 3 |
| Tickets: estimated cost per run at list prices when run, median | $0.0624 to $0.0700 | $0.958 | $0.266 | $0.195 to $0.215 | $0.0114 to $0.0125, 2 of 3 runs passed |
The table scrolls sideways on a small screen.
Scores count every run; costs use passed runs only. One GPT-6 Luna tickets run added tests inside an existing test file, which the gate counts as editing it. Runs from GPT-6.1 Terra 26 October, Claude Opus 5.5 30 September, Claude Sonnet 5.5 30 September, GPT-6.1 Sol 30 September and GPT-6 Luna 7 October, 2026. GPT-6 Luna's are its medium-effort runs from the Haiku vs Luna page.
How I ran it#
Background and method
GPT-6.1 Terra ran in Codex CLI 0.159.0. On this page Claude Opus 5.5 ran in Claude Code 2.1.284, Claude Sonnet 5.5 in Claude Code 2.1.284, GPT-6.1 Sol in Codex CLI 0.159.0 and GPT-6 Luna in Codex CLI 0.159.0, all at medium effort, with the account's apps, plugins and connectors off. All five ran in Docker on my subscriptions, with no API keys.
Time to finish is the whole run on one short explain task, from starting the tool to its exit, so it includes start-up. A run passes when the answer names the month logic and the ValueError. The five took turns. Output speed is a separate batch on a long walkthrough of the same file, four models taking turns, each answer counted with one tokenizer (OpenAI's o200k) over the seconds from its first text to its last. Claude Sonnet 5.5 was not in that batch. The same day, a first speed batch with GPT-6.1 Terra, Claude Sonnet 5.5 and GPT-6.1 Sol (18 runs), a speed batch with GPT-6.1 Terra, Claude Opus 5.5, Claude Sonnet 5.5 and GPT-6.1 Sol that I stopped after 6 runs to add GPT-6 Luna and a first output-speed batch with GPT-6.1 Terra and GPT-6.1 Sol (12 runs) also ran; their runs are in the data file and counted, and the charts draw the last batch of each.
The real app work is a bug hunt with 20 planted bugs and three sprint tickets in a small TypeScript app, graded by hidden tests, three runs each. Terra's are from its release day; the others use their published runs of the same tasks.
Costs are list-price estimates from each passed run's tokens, counting the warm-up request Codex sends first. GPT-6.1 Terra is $1 per million input tokens, $0.05 cached and $5 output, and GPT-6.1 Sol $2, $0.10 and $10. GPT costs are a range because Codex logs 0 cache writes on every run. The GPT models drew on my ChatGPT plan, and the Claude models on my Claude plan.
The run records are in results.json, under launch35_timing, launch35_tps, launch35_runs and launch35_real_runs, and the others' real app work under bughunt_runs and h2h_real_runs.