Claude Opus 5.5, rechecked after posts said it got worse
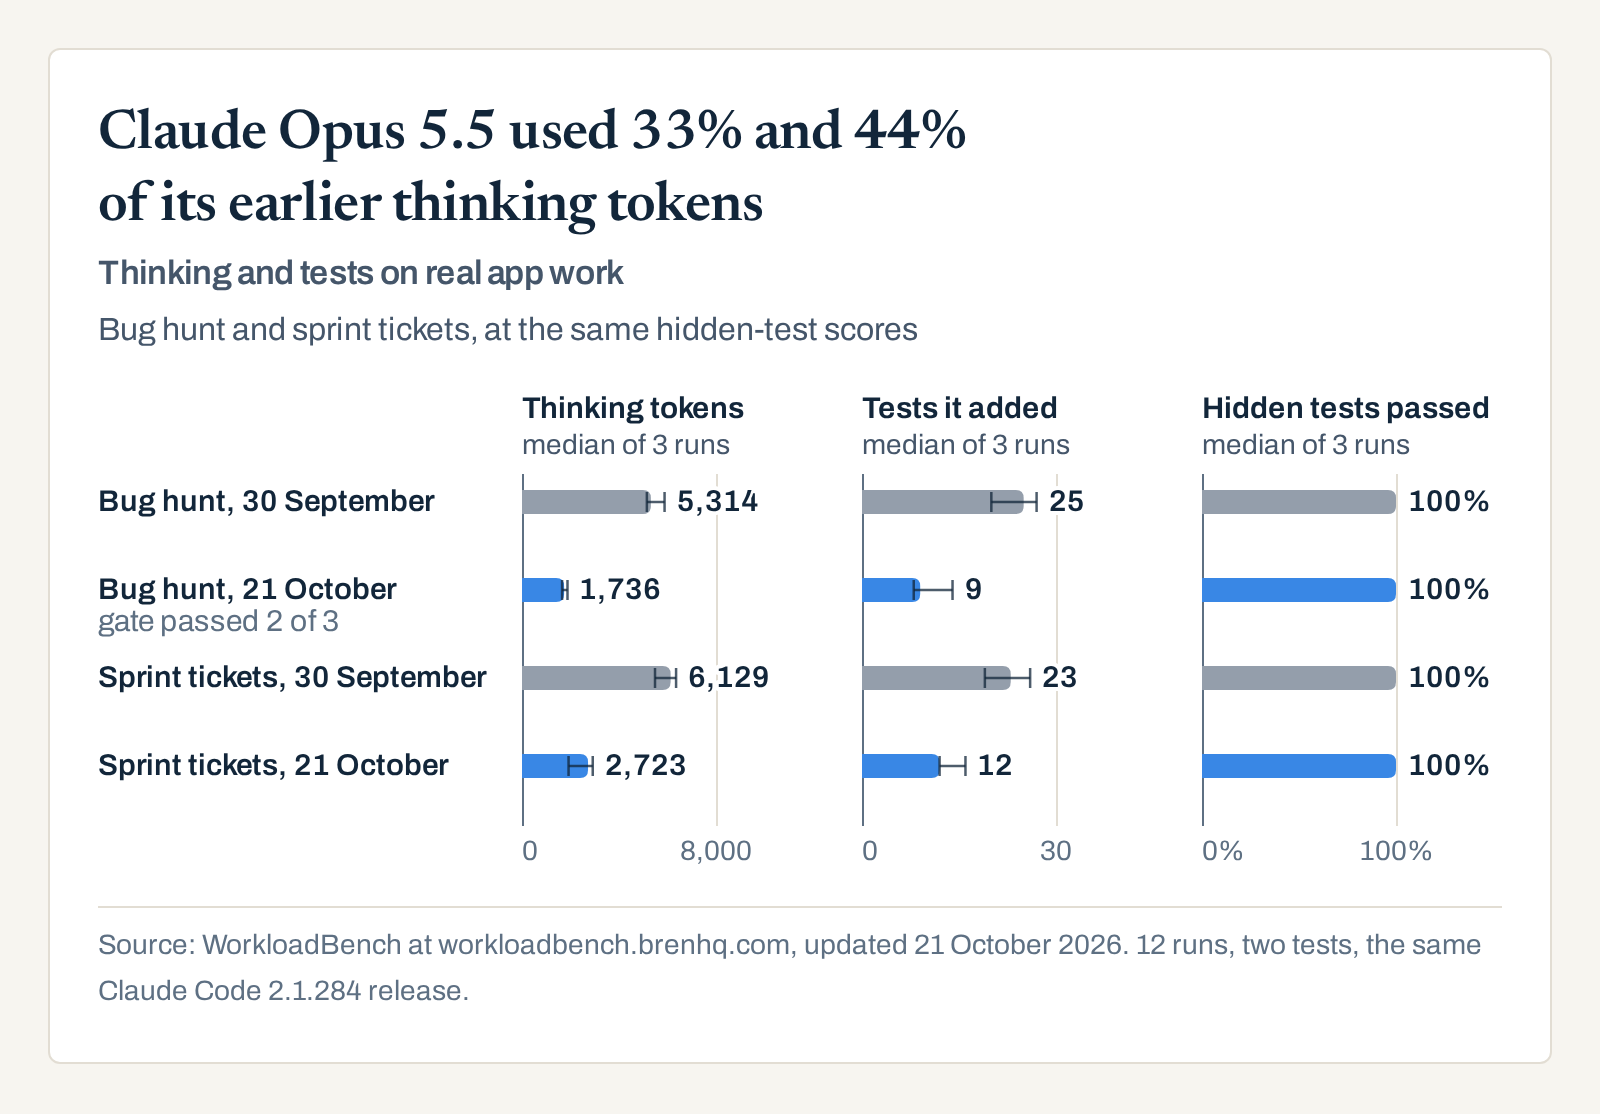
Same hidden-test scores as before, though one bug-hunt run failed its gate. On the bug hunt and tickets tests it used 33% and 44% of its earlier thinking tokens.
Real app work#
Thinking and tests on real app work
On the bug hunt and sprint tickets it used 33% and 44% of its earlier thinking tokens and added fewer tests, at the same hidden-test scores.
One recheck bug hunt run edited an existing test file, which the prompt says not to do, so its gate failed. The grader puts the original tests back first, so its hidden-test score stands.
Source: WorkloadBench at workloadbench.brenhq.com, updated 21 October 2026. 12 runs, two tests, the same Claude Code 2.1.284 release and settings.
Notes
The bug hunt is a small TypeScript web app with 20 planted bugs; sprint tickets is the same app with three tickets and 17 hidden checks. Hidden tests the model never sees score both.
Thinking tokens are the tokens Claude Code's own usage report counts as thinking in each run. Tests it added counts new test cases in the run's diff.
A run that edits an existing test file fails its gate. Its hidden-test score still counts, because the grader puts the original tests back first.
Every check#
| Check | Earlier, 22 September to 2 October 2026 | Recheck, 21 October 2026 |
|---|---|---|
| Four small coding tasks, every setup: runs that passed | 60 of 60 | 60 of 60 |
| ASD-STE100 instruction on the explain task: runs that passed | 3 of 3 | 3 of 3 |
| Held-out tests on the coding runs: passed | 45 of 45 | 45 of 45 |
| Bug hunt: bugs fixed of 20, each run | 20, 20, 20 of 20 | 20, 20, 20 of 20 |
| Bug hunt: runs whose gate passed | 3 of 3 | 2 of 3 |
| Sprint tickets: hidden checks passed, each run | 17, 17, 17 of 17 | 17, 17, 17 of 17 |
| Sprint tickets: runs whose gate passed | 3 of 3 | 3 of 3 |
Small tasks#
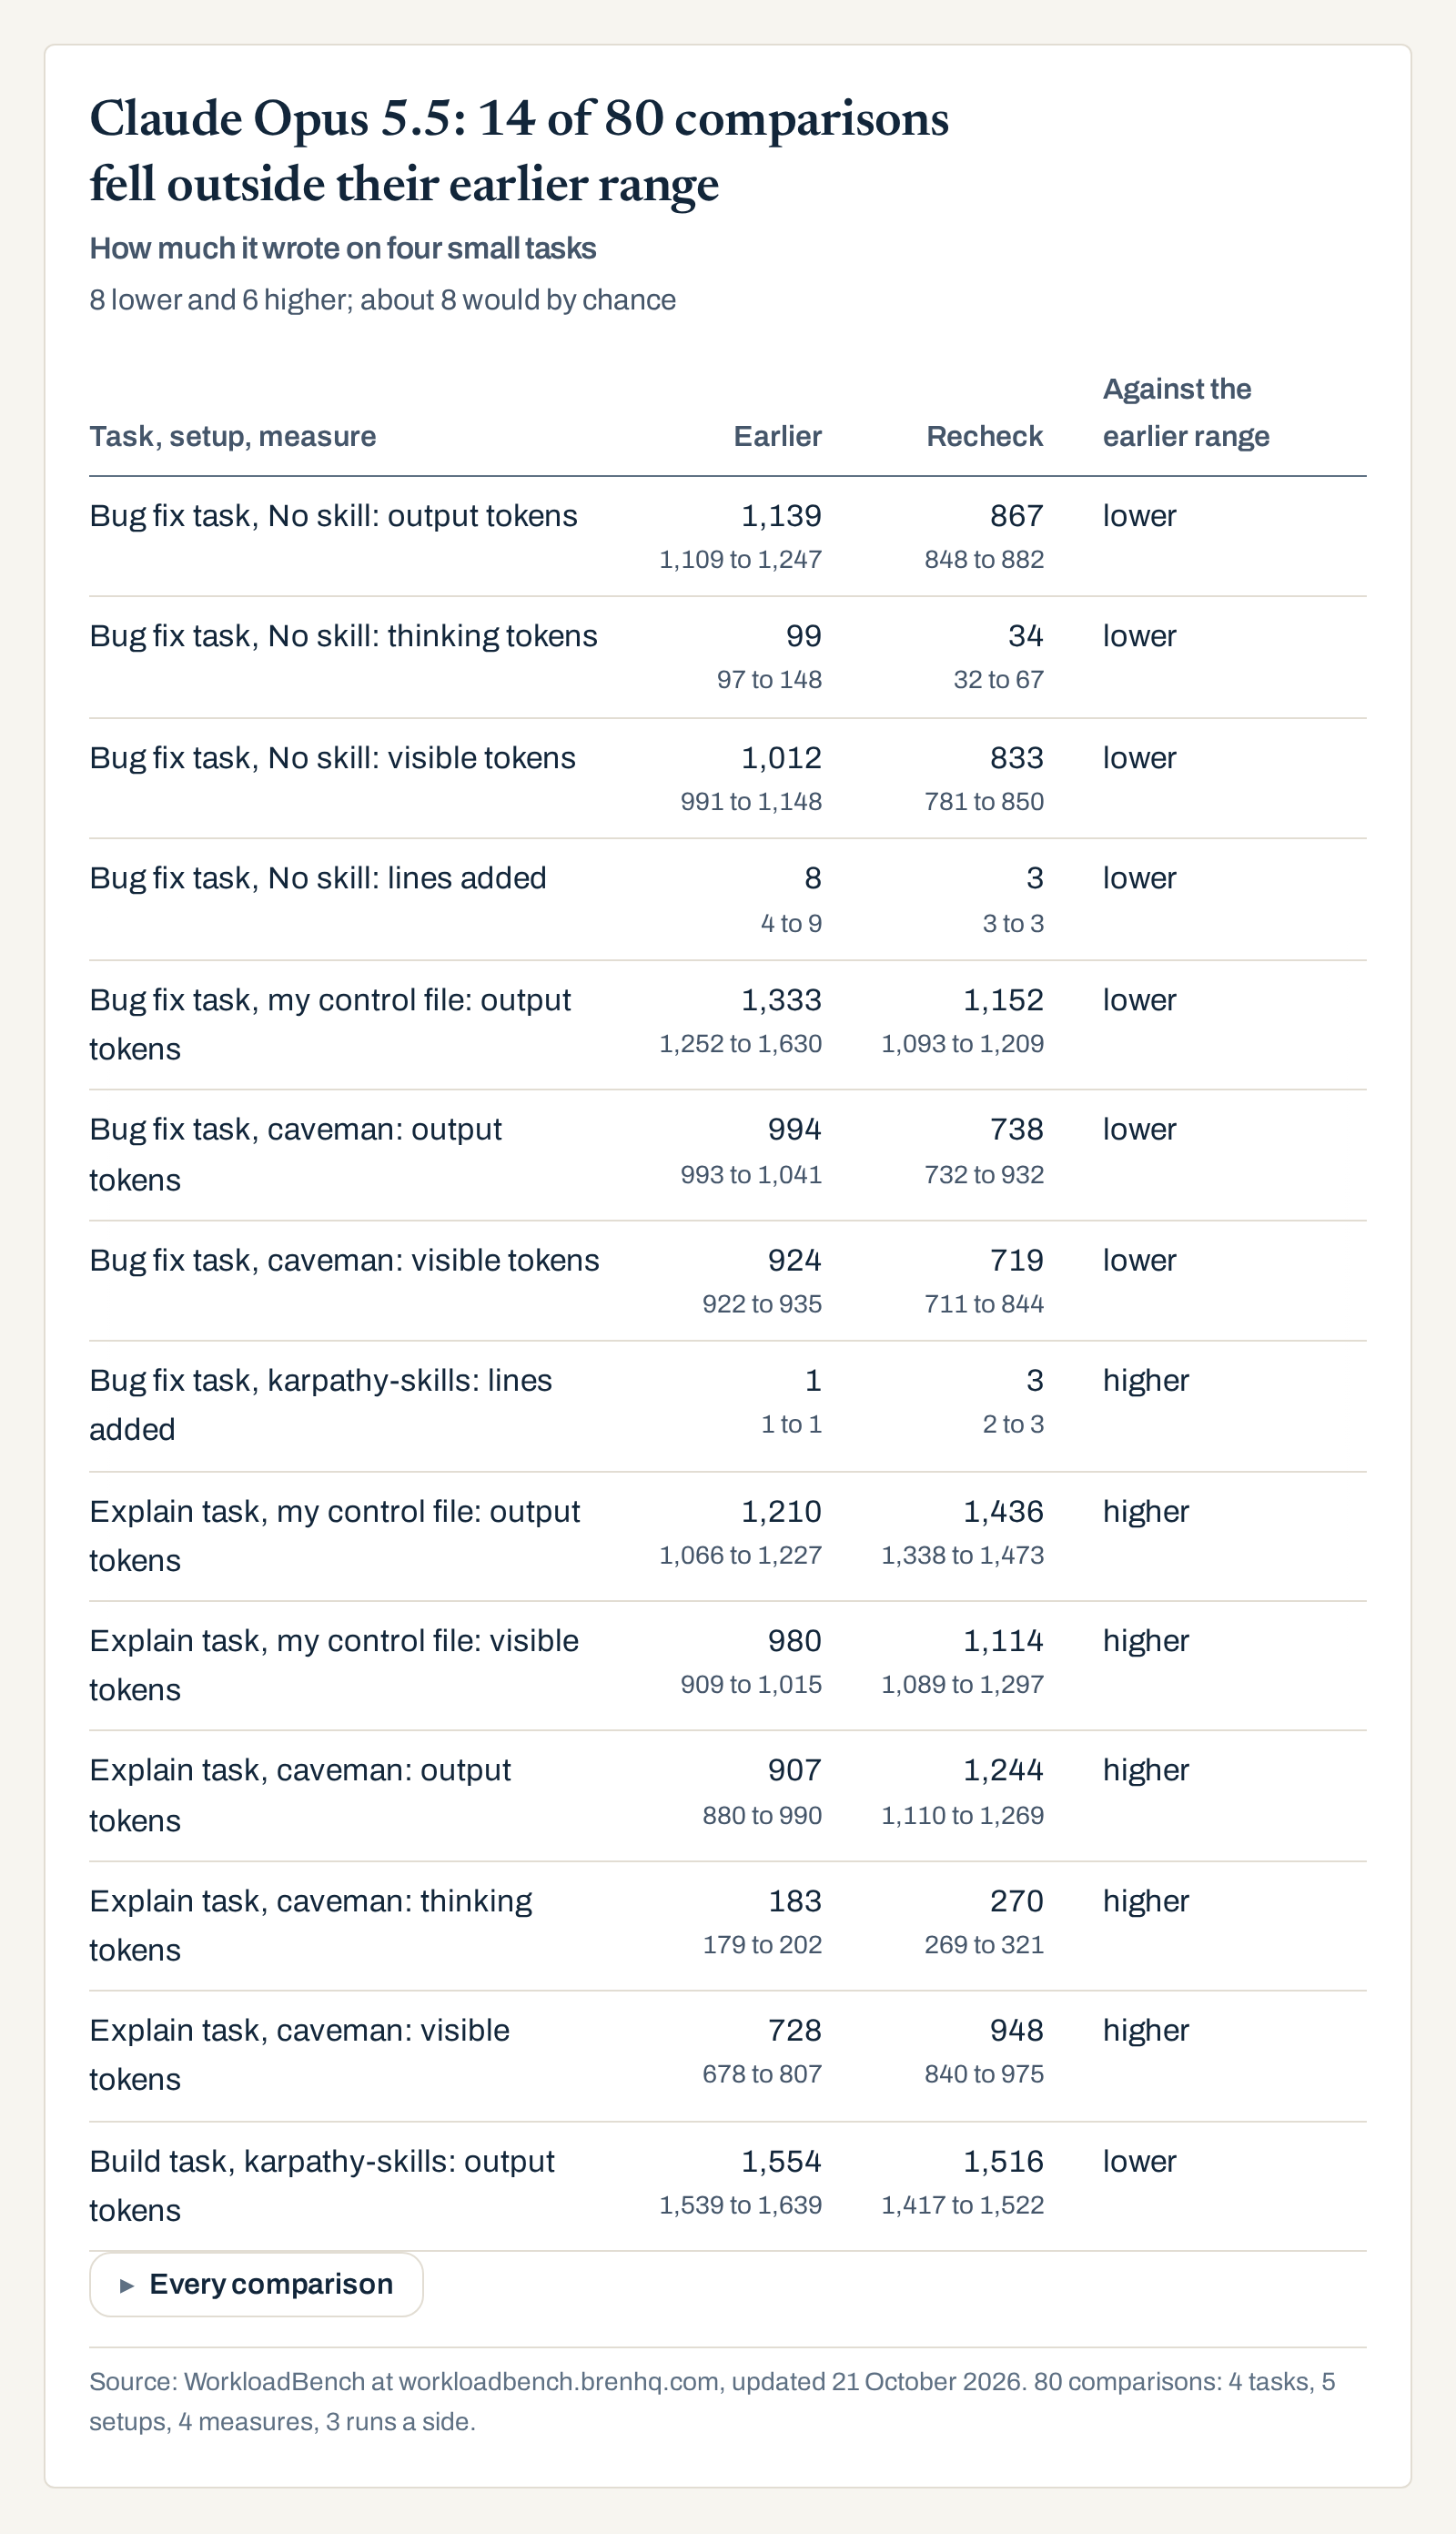
How much it wrote on four small tasks
14 of 80 comparisons fell outside their earlier range: 8 lower and 6 higher. About 8 would by chance.
The feature, bug fix and build tasks' earlier runs used Claude Code 2.1.280 with the account's extras on, so they can't separate a model change from a setup change; the explain task ran on the same setup both times.
| Task, setup, measure | Earlier | Recheck | Against the earlier range |
|---|---|---|---|
| Bug fix task, No skill: output tokens | 1,1391,109 to 1,247 | 867848 to 882 | lower |
| Bug fix task, No skill: thinking tokens | 9997 to 148 | 3432 to 67 | lower |
| Bug fix task, No skill: visible tokens | 1,012991 to 1,148 | 833781 to 850 | lower |
| Bug fix task, No skill: lines added | 84 to 9 | 33 to 3 | lower |
| Bug fix task, my control file: output tokens | 1,3331,252 to 1,630 | 1,1521,093 to 1,209 | lower |
| Bug fix task, caveman: output tokens | 994993 to 1,041 | 738732 to 932 | lower |
| Bug fix task, caveman: visible tokens | 924922 to 935 | 719711 to 844 | lower |
| Bug fix task, karpathy-skills: lines added | 11 to 1 | 32 to 3 | higher |
| Explain task, my control file: output tokens | 1,2101,066 to 1,227 | 1,4361,338 to 1,473 | higher |
| Explain task, my control file: visible tokens | 980909 to 1,015 | 1,1141,089 to 1,297 | higher |
| Explain task, caveman: output tokens | 907880 to 990 | 1,2441,110 to 1,269 | higher |
| Explain task, caveman: thinking tokens | 183179 to 202 | 270269 to 321 | higher |
| Explain task, caveman: visible tokens | 728678 to 807 | 948840 to 975 | higher |
| Build task, karpathy-skills: output tokens | 1,5541,539 to 1,639 | 1,5161,417 to 1,522 | lower |
Every comparison
| Task, setup, measure | Earlier | Recheck | Against the earlier range |
|---|---|---|---|
| Feature task, No skill: output tokens | 652574 to 693 | 691611 to 694 | overlap |
| Feature task, No skill: thinking tokens | 00 to 0 | 00 to 29 | overlap |
| Feature task, No skill: visible tokens | 652574 to 693 | 665611 to 691 | overlap |
| Feature task, No skill: lines added | 66 to 6 | 66 to 6 | overlap |
| Feature task, my control file: output tokens | 933896 to 956 | 773722 to 973 | overlap |
| Feature task, my control file: thinking tokens | 3831 to 39 | 00 to 32 | overlap |
| Feature task, my control file: visible tokens | 895865 to 917 | 773690 to 973 | overlap |
| Feature task, my control file: lines added | 76 to 7 | 66 to 7 | overlap |
| Feature task, caveman: output tokens | 619570 to 803 | 571540 to 593 | overlap |
| Feature task, caveman: thinking tokens | 200 to 35 | 00 to 0 | overlap |
| Feature task, caveman: visible tokens | 599570 to 768 | 571540 to 593 | overlap |
| Feature task, caveman: lines added | 66 to 6 | 66 to 6 | overlap |
| Feature task, ponytail: output tokens | 651616 to 689 | 601576 to 653 | overlap |
| Feature task, ponytail: thinking tokens | 230 to 33 | 00 to 0 | overlap |
| Feature task, ponytail: visible tokens | 628583 to 689 | 601576 to 653 | overlap |
| Feature task, ponytail: lines added | 66 to 6 | 66 to 6 | overlap |
| Feature task, karpathy-skills: output tokens | 772751 to 786 | 806783 to 830 | overlap |
| Feature task, karpathy-skills: thinking tokens | 2822 to 51 | 210 to 27 | overlap |
| Feature task, karpathy-skills: visible tokens | 744700 to 764 | 806756 to 809 | overlap |
| Feature task, karpathy-skills: lines added | 66 to 6 | 65 to 6 | overlap |
| Bug fix task, No skill: output tokens | 1,1391,109 to 1,247 | 867848 to 882 | lower |
| Bug fix task, No skill: thinking tokens | 9997 to 148 | 3432 to 67 | lower |
| Bug fix task, No skill: visible tokens | 1,012991 to 1,148 | 833781 to 850 | lower |
| Bug fix task, No skill: lines added | 84 to 9 | 33 to 3 | lower |
| Bug fix task, my control file: output tokens | 1,3331,252 to 1,630 | 1,1521,093 to 1,209 | lower |
| Bug fix task, my control file: thinking tokens | 235115 to 292 | 137101 to 151 | overlap |
| Bug fix task, my control file: visible tokens | 1,2181,017 to 1,338 | 1,051942 to 1,072 | overlap |
| Bug fix task, my control file: lines added | 44 to 13 | 44 to 9 | overlap |
| Bug fix task, caveman: output tokens | 994993 to 1,041 | 738732 to 932 | lower |
| Bug fix task, caveman: thinking tokens | 7269 to 106 | 2119 to 88 | overlap |
| Bug fix task, caveman: visible tokens | 924922 to 935 | 719711 to 844 | lower |
| Bug fix task, caveman: lines added | 44 to 4 | 33 to 4 | overlap |
| Bug fix task, ponytail: output tokens | 1,2411,126 to 1,417 | 1,4201,260 to 1,457 | overlap |
| Bug fix task, ponytail: thinking tokens | 357235 to 393 | 376247 to 462 | overlap |
| Bug fix task, ponytail: visible tokens | 891884 to 1,024 | 1,013958 to 1,081 | overlap |
| Bug fix task, ponytail: lines added | 22 to 2 | 22 to 5 | overlap |
| Bug fix task, karpathy-skills: output tokens | 1,045903 to 1,053 | 1,0671,021 to 1,093 | overlap |
| Bug fix task, karpathy-skills: thinking tokens | 128126 to 178 | 8379 to 184 | overlap |
| Bug fix task, karpathy-skills: visible tokens | 875775 to 919 | 988837 to 1,010 | overlap |
| Bug fix task, karpathy-skills: lines added | 11 to 1 | 32 to 3 | higher |
| Explain task, No skill: output tokens | 1,1671,066 to 1,429 | 1,3191,270 to 1,634 | overlap |
| Explain task, No skill: thinking tokens | 179179 to 313 | 281212 to 465 | overlap |
| Explain task, No skill: visible tokens | 988887 to 1,116 | 1,0581,038 to 1,169 | overlap |
| Explain task, No skill: lines added | 00 to 0 | 00 to 0 | overlap |
| Explain task, my control file: output tokens | 1,2101,066 to 1,227 | 1,4361,338 to 1,473 | higher |
| Explain task, my control file: thinking tokens | 212157 to 230 | 249176 to 322 | overlap |
| Explain task, my control file: visible tokens | 980909 to 1,015 | 1,1141,089 to 1,297 | higher |
| Explain task, my control file: lines added | 00 to 0 | 00 to 0 | overlap |
| Explain task, caveman: output tokens | 907880 to 990 | 1,2441,110 to 1,269 | higher |
| Explain task, caveman: thinking tokens | 183179 to 202 | 270269 to 321 | higher |
| Explain task, caveman: visible tokens | 728678 to 807 | 948840 to 975 | higher |
| Explain task, caveman: lines added | 00 to 0 | 00 to 0 | overlap |
| Explain task, ponytail: output tokens | 1,2721,010 to 1,294 | 1,3061,212 to 1,556 | overlap |
| Explain task, ponytail: thinking tokens | 248100 to 305 | 267206 to 327 | overlap |
| Explain task, ponytail: visible tokens | 967910 to 1,046 | 1,0391,006 to 1,229 | overlap |
| Explain task, ponytail: lines added | 00 to 0 | 00 to 0 | overlap |
| Explain task, karpathy-skills: output tokens | 1,2231,176 to 1,420 | 1,4861,367 to 1,536 | overlap |
| Explain task, karpathy-skills: thinking tokens | 230109 to 374 | 320296 to 342 | overlap |
| Explain task, karpathy-skills: visible tokens | 1,046946 to 1,114 | 1,1661,071 to 1,194 | overlap |
| Explain task, karpathy-skills: lines added | 00 to 0 | 00 to 0 | overlap |
| Build task, No skill: output tokens | 1,6591,496 to 1,681 | 1,5521,495 to 1,630 | overlap |
| Build task, No skill: thinking tokens | 9883 to 234 | 7676 to 84 | overlap |
| Build task, No skill: visible tokens | 1,4471,398 to 1,576 | 1,4681,419 to 1,554 | overlap |
| Build task, No skill: lines added | 5453 to 56 | 5653 to 56 | overlap |
| Build task, my control file: output tokens | 2,0281,874 to 2,048 | 1,8321,815 to 2,064 | overlap |
| Build task, my control file: thinking tokens | 236194 to 260 | 175161 to 201 | overlap |
| Build task, my control file: visible tokens | 1,7921,614 to 1,854 | 1,6541,631 to 1,889 | overlap |
| Build task, my control file: lines added | 6663 to 66 | 6160 to 63 | overlap |
| Build task, caveman: output tokens | 1,6011,534 to 1,617 | 1,4961,473 to 1,569 | overlap |
| Build task, caveman: thinking tokens | 116101 to 167 | 8888 to 117 | overlap |
| Build task, caveman: visible tokens | 1,4501,418 to 1,500 | 1,3851,379 to 1,481 | overlap |
| Build task, caveman: lines added | 5656 to 58 | 5353 to 56 | overlap |
| Build task, ponytail: output tokens | 1,4851,358 to 1,674 | 1,5361,480 to 1,696 | overlap |
| Build task, ponytail: thinking tokens | 201188 to 229 | 231156 to 234 | overlap |
| Build task, ponytail: visible tokens | 1,2841,170 to 1,445 | 1,3241,305 to 1,462 | overlap |
| Build task, ponytail: lines added | 4038 to 44 | 4141 to 43 | overlap |
| Build task, karpathy-skills: output tokens | 1,5541,539 to 1,639 | 1,5161,417 to 1,522 | lower |
| Build task, karpathy-skills: thinking tokens | 218169 to 242 | 125106 to 193 | overlap |
| Build task, karpathy-skills: visible tokens | 1,3701,336 to 1,397 | 1,3291,292 to 1,410 | overlap |
| Build task, karpathy-skills: lines added | 4140 to 43 | 4140 to 43 | overlap |
Source: WorkloadBench at workloadbench.brenhq.com, updated 21 October 2026. 80 comparisons: 4 tasks, 5 setups, 4 measures, 3 runs a side.
Notes
A measure counts as moved only when the recheck's three runs and the earlier three don't overlap. If runs varied at random with no ties, two sets of three would miss each other 1 time in 10, so about 8 of 80 would by chance; tied counts make it rarer.
The recheck used Claude Code 2.1.284 with the account's extras off.
Visible tokens are output tokens minus thinking tokens. Lines added counts lines the run added to the task's files.
Deep suite#
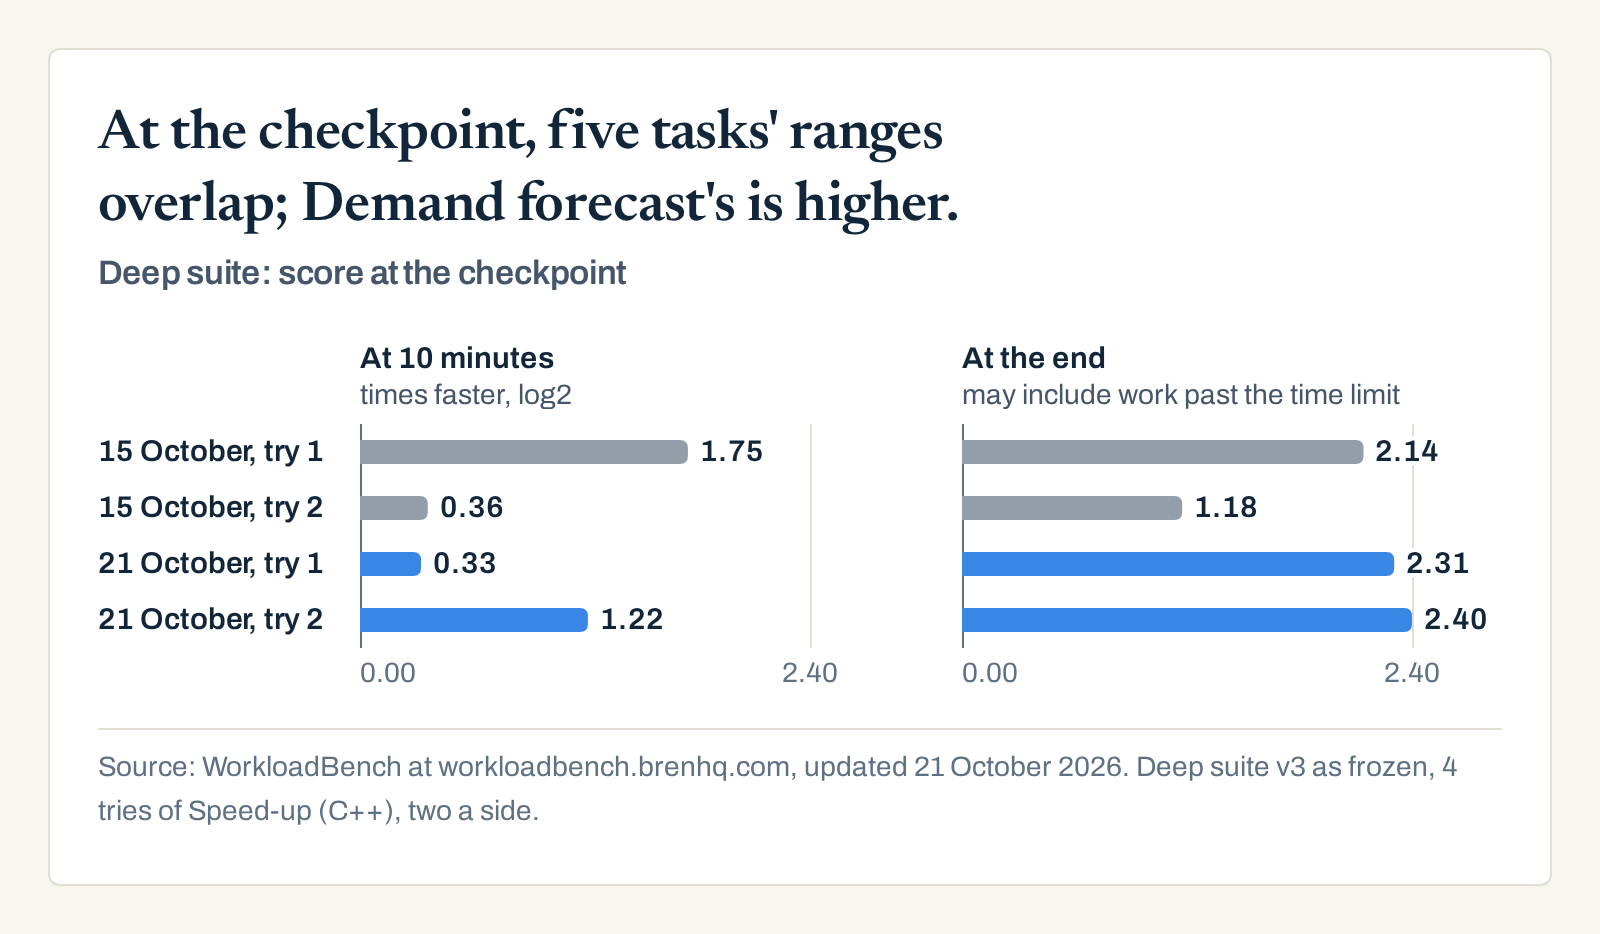
Deep suite: score at the checkpoint
At the checkpoint, five tasks' ranges overlap; Demand forecast's is higher.
5 of the recheck's 8 tries that reached the time limit kept making tool calls after it; 0 of 9 did on 15 October.
Source: WorkloadBench at workloadbench.brenhq.com, updated 21 October 2026. Deep suite v3 as frozen, 4 tries of Speed-up (C++), two a side.
Notes
Each try is graded at a checkpoint partway through (10 minutes; 5 for the job service) and at the end. The checkpoint is the same moment in both rounds.
Tries 1 and 2 use the same seeds and data in both rounds. The tasks, time limits and images are the frozen suite's; an invalid try scores 0.
A final score can include work after the time limit: 5 of the recheck's 8 tries that reached the limit kept making tool calls after it, against 0 of 9 on 15 October, with the same Claude Code release. The logs don't say why. So only the checkpoint gets a verdict here.
Speed#
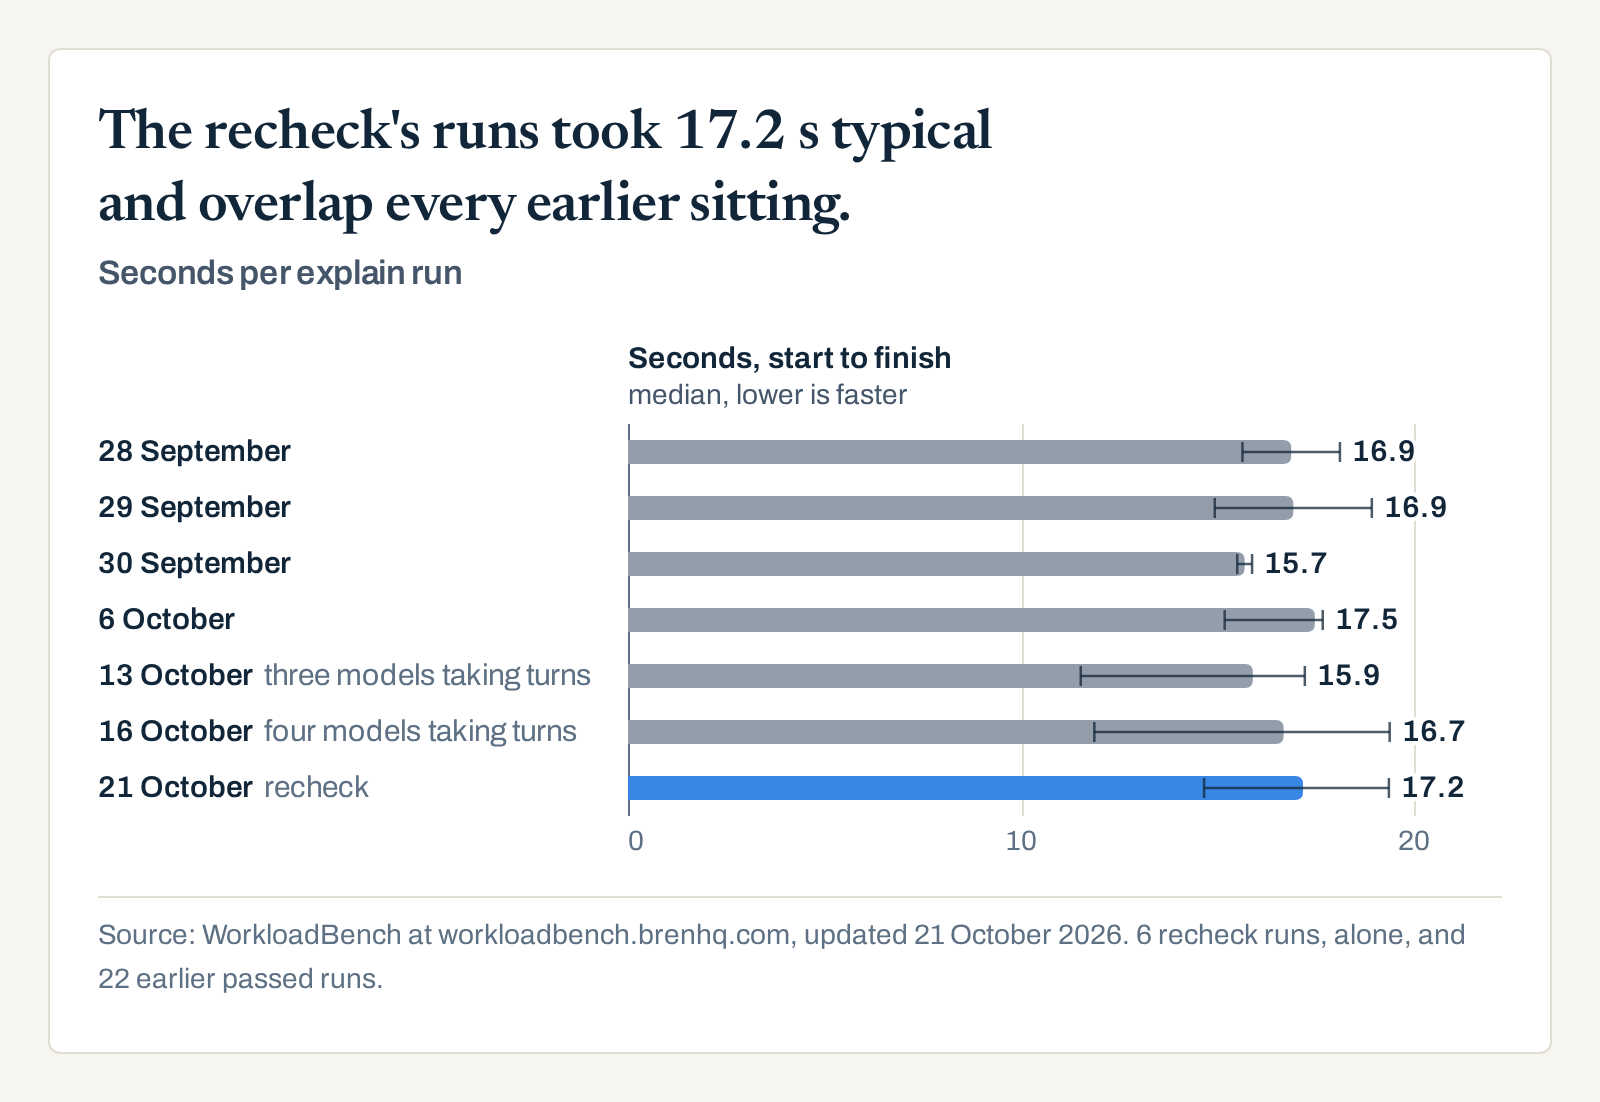
Seconds per explain run
The recheck's runs took 17.2 s typical and overlap every earlier sitting.
Source: WorkloadBench at workloadbench.brenhq.com, updated 21 October 2026. 6 recheck runs, alone, and 22 earlier passed runs.
Notes
The explain task, start to finish: the tool reads a small file and explains it. Each sitting is compared on its own; days and times of day differ.
Passed runs only. The recheck's runs ran one after another with nothing else on the machine.
The slowest recheck run took 19.4 s, 3.4 s of it waiting for the first token.
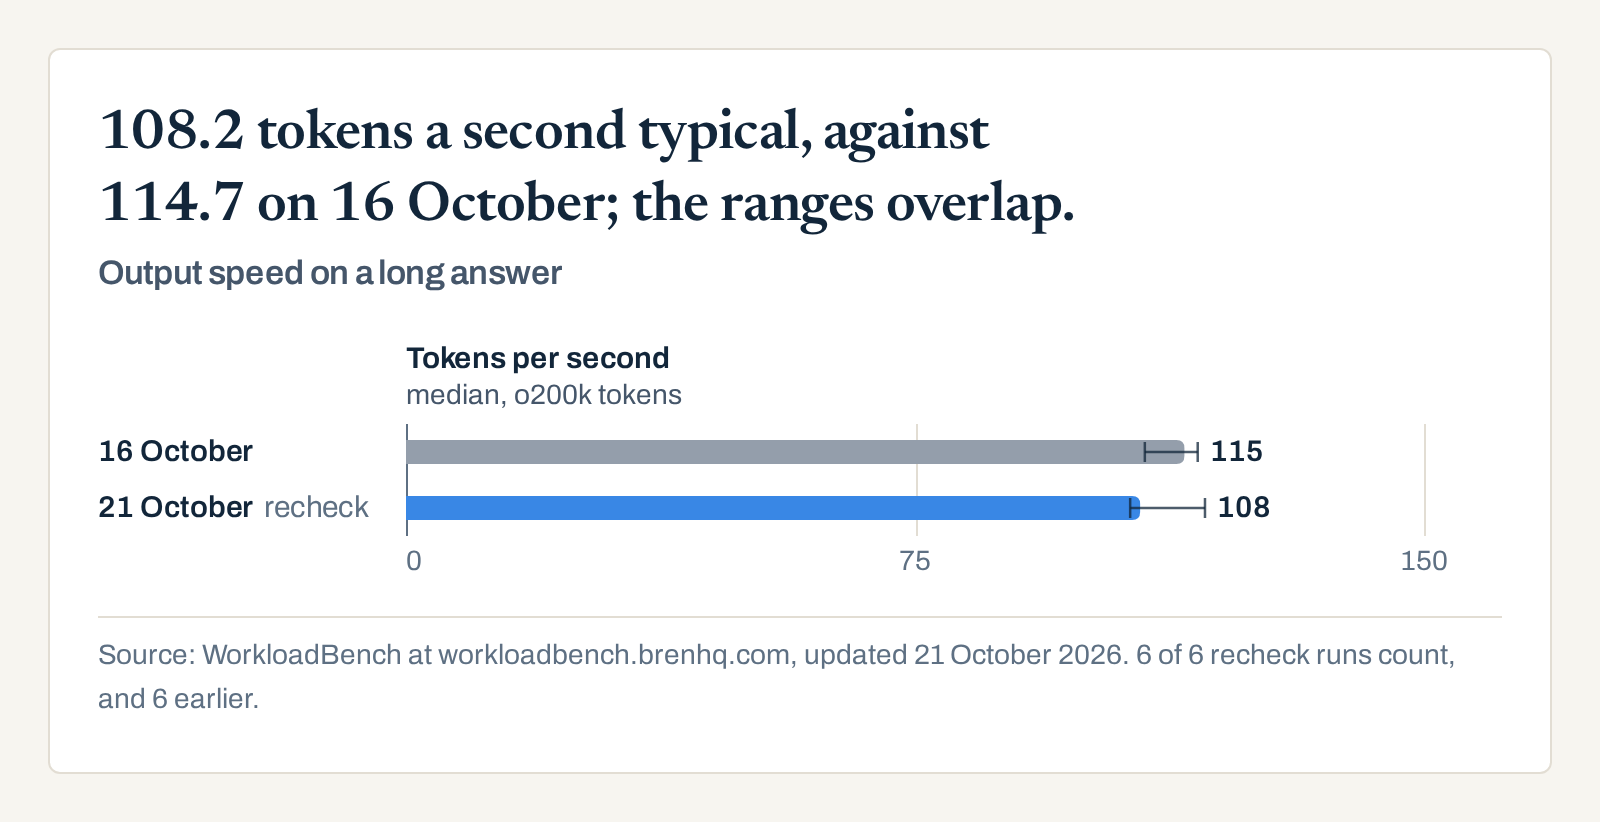
Output speed on a long answer
108.2 tokens a second typical, against 114.7 on 16 October; the ranges overlap.
Source: WorkloadBench at workloadbench.brenhq.com, updated 21 October 2026. 6 of 6 recheck runs count, and 6 earlier.
Notes
The final answer's text counted with one tokenizer (OpenAI's o200k_base) over the seconds from its first piece of text to its last, as it reached my terminal. A run counts when it passed and its text arrived in 20 or more bursts.
The same long-answer task as the Muse Wonder page's.
Which model answered#
Claude Code's own usage report lists only Claude Opus 5.5 on all 69 quick-suite runs in the recheck, and on all 69 earlier ones. Every one of the 1,133 deep-suite replies in the recheck names it as the model, as all 1,146 did before. The CLI sent medium effort on every timed run, as before.
How I ran it#
Background and method
Posts on X on 21 October 2026 said Claude Opus 5.5 had gotten worse in the last day. I ran the same tests again the same way: Claude Code 2.1.284, the same effort setting, the account's extras off, in the bench's Docker container on my own subscription. Every run is counted.
The baseline is this model's published runs from before the recheck. The bench image was rebuilt between the two rounds; the deep suite's images are frozen. Three of the four small tasks also changed setup, as the small-task notes say.
Limits: three runs a side on each small task and real-app test, two tries a side on each deep task; the correctness tests were already at their ceiling, so they can show a drop but not a gain; the days and times of day differ. A recheck shows whether this model's work on these tasks changed, on this account and this CLI release. It can't show why, or how the model is trained or served.