GPT-6.1 Sol, rechecked after posts said it got better
Same hidden-test scores as before. Every real-app measure overlapped its earlier range.
Real app work#
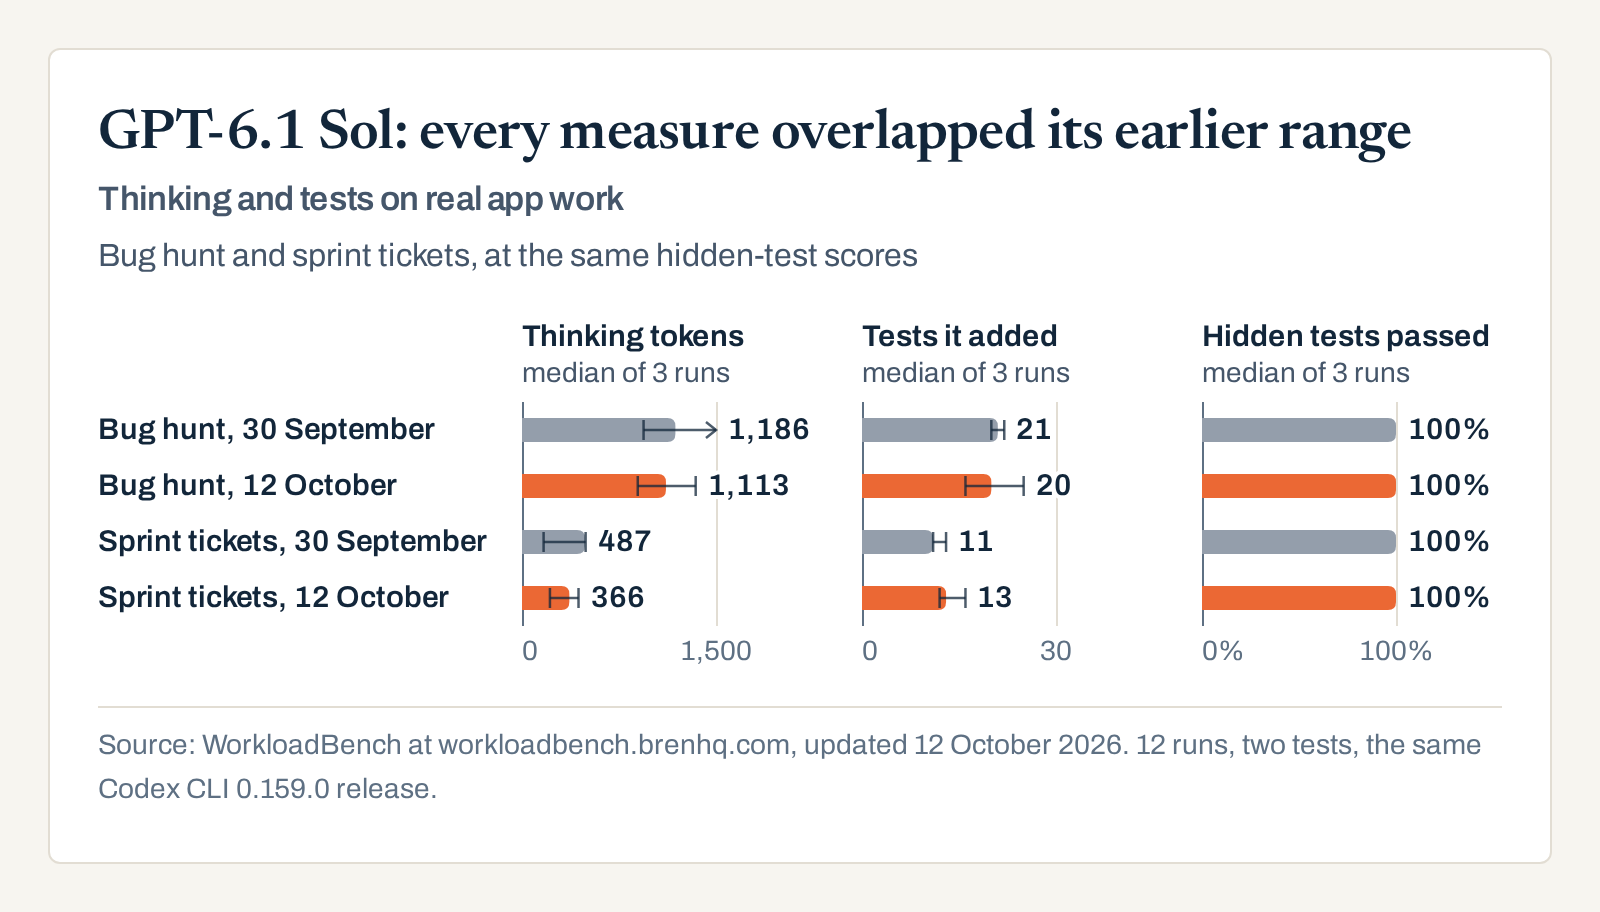
Thinking and tests on real app work
Every real-app measure overlapped its earlier range, at the same hidden-test scores.
Source: WorkloadBench at workloadbench.brenhq.com, updated 12 October 2026. 12 runs, two tests, the same Codex CLI 0.159.0 release and settings.
Notes
The bug hunt is a small TypeScript web app with 20 planted bugs; sprint tickets is the same app with three tickets and 17 hidden checks. Hidden tests the model never sees score both.
Thinking tokens are the tokens Claude Code's own usage report counts as thinking in each run. Tests it added counts new test cases in the run's diff.
A run that edits an existing test file fails its gate. Its hidden-test score still counts, because the grader puts the original tests back first.
Every check#
| Check | Earlier, 29 September to 2 October 2026 | Recheck, 12 October 2026 |
|---|---|---|
| Four small coding tasks, every setup: runs that passed | 60 of 60 | 60 of 60 |
| ASD-STE100 instruction on the explain task: runs that passed | 3 of 3 | 3 of 3 |
| Held-out tests on the coding runs: passed | 45 of 45 | 45 of 45 |
| Bug hunt: bugs fixed of 20, each run | 20, 20, 20 of 20 | 20, 20, 20 of 20 |
| Bug hunt: runs whose gate passed | 3 of 3 | 3 of 3 |
| Sprint tickets: hidden checks passed, each run | 17, 17, 17 of 17 | 17, 17, 17 of 17 |
| Sprint tickets: runs whose gate passed | 3 of 3 | 3 of 3 |
Small tasks#
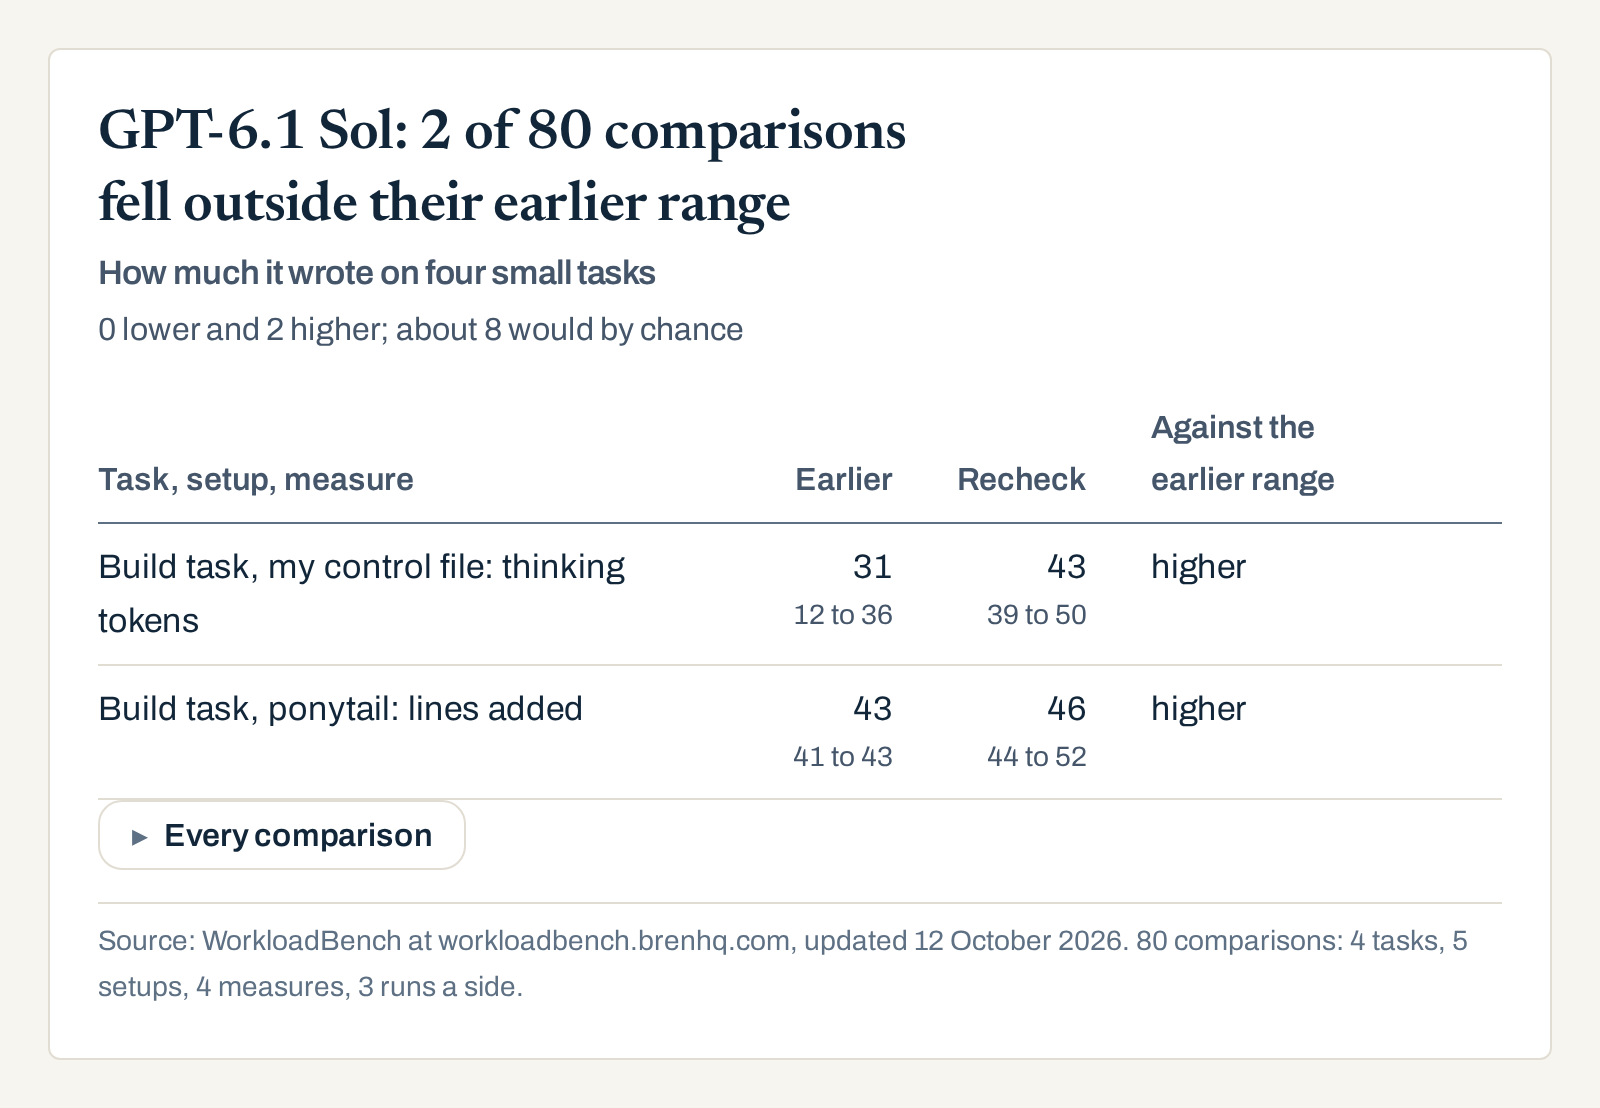
How much it wrote on four small tasks
2 of 80 comparisons fell outside their earlier range: 0 lower and 2 higher. About 8 would by chance.
The feature, bug fix, explain and build tasks' earlier runs had the account's extras on, the recheck's off, so they can't separate a model change from a setup change.
| Task, setup, measure | Earlier | Recheck | Against the earlier range |
|---|---|---|---|
| Build task, my control file: thinking tokens | 3112 to 36 | 4339 to 50 | higher |
| Build task, ponytail: lines added | 4341 to 43 | 4644 to 52 | higher |
Every comparison
| Task, setup, measure | Earlier | Recheck | Against the earlier range |
|---|---|---|---|
| Feature task, No skill: output tokens | 669569 to 706 | 588502 to 606 | overlap |
| Feature task, No skill: thinking tokens | 1210 to 14 | 00 to 12 | overlap |
| Feature task, No skill: visible tokens | 659557 to 692 | 588502 to 594 | overlap |
| Feature task, No skill: lines added | 76 to 7 | 65 to 6 | overlap |
| Feature task, my control file: output tokens | 561443 to 634 | 636604 to 703 | overlap |
| Feature task, my control file: thinking tokens | 00 to 28 | 1310 to 27 | overlap |
| Feature task, my control file: visible tokens | 561443 to 606 | 609591 to 693 | overlap |
| Feature task, my control file: lines added | 66 to 6 | 66 to 7 | overlap |
| Feature task, caveman: output tokens | 542398 to 555 | 496445 to 500 | overlap |
| Feature task, caveman: thinking tokens | 00 to 0 | 00 to 0 | overlap |
| Feature task, caveman: visible tokens | 542398 to 555 | 496445 to 500 | overlap |
| Feature task, caveman: lines added | 66 to 6 | 66 to 9 | overlap |
| Feature task, ponytail: output tokens | 615536 to 658 | 598597 to 612 | overlap |
| Feature task, ponytail: thinking tokens | 2722 to 58 | 3220 to 38 | overlap |
| Feature task, ponytail: visible tokens | 588514 to 600 | 577560 to 580 | overlap |
| Feature task, ponytail: lines added | 55 to 5 | 55 to 5 | overlap |
| Feature task, karpathy-skills: output tokens | 571556 to 620 | 551504 to 587 | overlap |
| Feature task, karpathy-skills: thinking tokens | 110 to 11 | 80 to 20 | overlap |
| Feature task, karpathy-skills: visible tokens | 560556 to 609 | 531496 to 587 | overlap |
| Feature task, karpathy-skills: lines added | 55 to 5 | 55 to 5 | overlap |
| Bug fix task, No skill: output tokens | 537498 to 652 | 599568 to 666 | overlap |
| Bug fix task, No skill: thinking tokens | 3921 to 49 | 2717 to 72 | overlap |
| Bug fix task, No skill: visible tokens | 498477 to 603 | 572551 to 594 | overlap |
| Bug fix task, No skill: lines added | 11 to 3 | 11 to 3 | overlap |
| Bug fix task, my control file: output tokens | 597583 to 630 | 571564 to 631 | overlap |
| Bug fix task, my control file: thinking tokens | 5234 to 59 | 3121 to 67 | overlap |
| Bug fix task, my control file: visible tokens | 549538 to 578 | 543540 to 564 | overlap |
| Bug fix task, my control file: lines added | 31 to 3 | 11 to 3 | overlap |
| Bug fix task, caveman: output tokens | 471381 to 486 | 470459 to 480 | overlap |
| Bug fix task, caveman: thinking tokens | 1913 to 28 | 3318 to 67 | overlap |
| Bug fix task, caveman: visible tokens | 443368 to 467 | 437413 to 441 | overlap |
| Bug fix task, caveman: lines added | 11 to 1 | 11 to 3 | overlap |
| Bug fix task, ponytail: output tokens | 555542 to 604 | 553518 to 591 | overlap |
| Bug fix task, ponytail: thinking tokens | 7759 to 77 | 8530 to 103 | overlap |
| Bug fix task, ponytail: visible tokens | 496465 to 527 | 468415 to 561 | overlap |
| Bug fix task, ponytail: lines added | 11 to 1 | 11 to 1 | overlap |
| Bug fix task, karpathy-skills: output tokens | 580561 to 625 | 520499 to 588 | overlap |
| Bug fix task, karpathy-skills: thinking tokens | 1613 to 28 | 1615 to 17 | overlap |
| Bug fix task, karpathy-skills: visible tokens | 567533 to 609 | 504484 to 571 | overlap |
| Bug fix task, karpathy-skills: lines added | 11 to 1 | 11 to 1 | overlap |
| Explain task, No skill: output tokens | 286232 to 302 | 295288 to 308 | overlap |
| Explain task, No skill: thinking tokens | 00 to 0 | 00 to 0 | overlap |
| Explain task, No skill: visible tokens | 286232 to 302 | 295288 to 308 | overlap |
| Explain task, No skill: lines added | 00 to 0 | 00 to 0 | overlap |
| Explain task, my control file: output tokens | 225216 to 226 | 221221 to 226 | overlap |
| Explain task, my control file: thinking tokens | 00 to 0 | 00 to 0 | overlap |
| Explain task, my control file: visible tokens | 225216 to 226 | 221221 to 226 | overlap |
| Explain task, my control file: lines added | 00 to 0 | 00 to 0 | overlap |
| Explain task, caveman: output tokens | 184173 to 186 | 186180 to 187 | overlap |
| Explain task, caveman: thinking tokens | 00 to 0 | 00 to 0 | overlap |
| Explain task, caveman: visible tokens | 184173 to 186 | 186180 to 187 | overlap |
| Explain task, caveman: lines added | 00 to 0 | 00 to 0 | overlap |
| Explain task, ponytail: output tokens | 211211 to 223 | 234215 to 275 | overlap |
| Explain task, ponytail: thinking tokens | 00 to 0 | 00 to 0 | overlap |
| Explain task, ponytail: visible tokens | 211211 to 223 | 234215 to 275 | overlap |
| Explain task, ponytail: lines added | 00 to 0 | 00 to 0 | overlap |
| Explain task, karpathy-skills: output tokens | 253237 to 262 | 255212 to 261 | overlap |
| Explain task, karpathy-skills: thinking tokens | 00 to 0 | 00 to 0 | overlap |
| Explain task, karpathy-skills: visible tokens | 253237 to 262 | 255212 to 261 | overlap |
| Explain task, karpathy-skills: lines added | 00 to 0 | 00 to 0 | overlap |
| Build task, No skill: output tokens | 1,026978 to 1,077 | 962956 to 1,062 | overlap |
| Build task, No skill: thinking tokens | 1812 to 19 | 1413 to 24 | overlap |
| Build task, No skill: visible tokens | 1,007966 to 1,059 | 949942 to 1,038 | overlap |
| Build task, No skill: lines added | 5050 to 54 | 5050 to 55 | overlap |
| Build task, my control file: output tokens | 1,1681,144 to 1,318 | 1,2091,188 to 1,234 | overlap |
| Build task, my control file: thinking tokens | 3112 to 36 | 4339 to 50 | higher |
| Build task, my control file: visible tokens | 1,1371,132 to 1,282 | 1,1661,149 to 1,184 | overlap |
| Build task, my control file: lines added | 6666 to 67 | 6767 to 70 | overlap |
| Build task, caveman: output tokens | 936896 to 1,082 | 1,0201,008 to 1,049 | overlap |
| Build task, caveman: thinking tokens | 00 to 44 | 3515 to 44 | overlap |
| Build task, caveman: visible tokens | 936896 to 1,038 | 993985 to 1,005 | overlap |
| Build task, caveman: lines added | 5751 to 60 | 5352 to 54 | overlap |
| Build task, ponytail: output tokens | 1,1241,044 to 1,180 | 1,1381,003 to 1,155 | overlap |
| Build task, ponytail: thinking tokens | 212109 to 265 | 145117 to 168 | overlap |
| Build task, ponytail: visible tokens | 915912 to 935 | 970886 to 1,010 | overlap |
| Build task, ponytail: lines added | 4341 to 43 | 4644 to 52 | higher |
| Build task, karpathy-skills: output tokens | 1,0421,035 to 1,060 | 1,049968 to 1,051 | overlap |
| Build task, karpathy-skills: thinking tokens | 8662 to 131 | 5146 to 75 | overlap |
| Build task, karpathy-skills: visible tokens | 974904 to 980 | 1,000893 to 1,003 | overlap |
| Build task, karpathy-skills: lines added | 4645 to 47 | 4645 to 48 | overlap |
Source: WorkloadBench at workloadbench.brenhq.com, updated 12 October 2026. 80 comparisons: 4 tasks, 5 setups, 4 measures, 3 runs a side.
Notes
A measure counts as moved only when the recheck's three runs and the earlier three don't overlap. If runs varied at random with no ties, two sets of three would miss each other 1 time in 10, so about 8 of 80 would by chance; tied counts make it rarer.
The recheck used Codex CLI 0.159.0 with the account's extras off.
Visible tokens are output tokens minus thinking tokens. Lines added counts lines the run added to the task's files.
Speed#
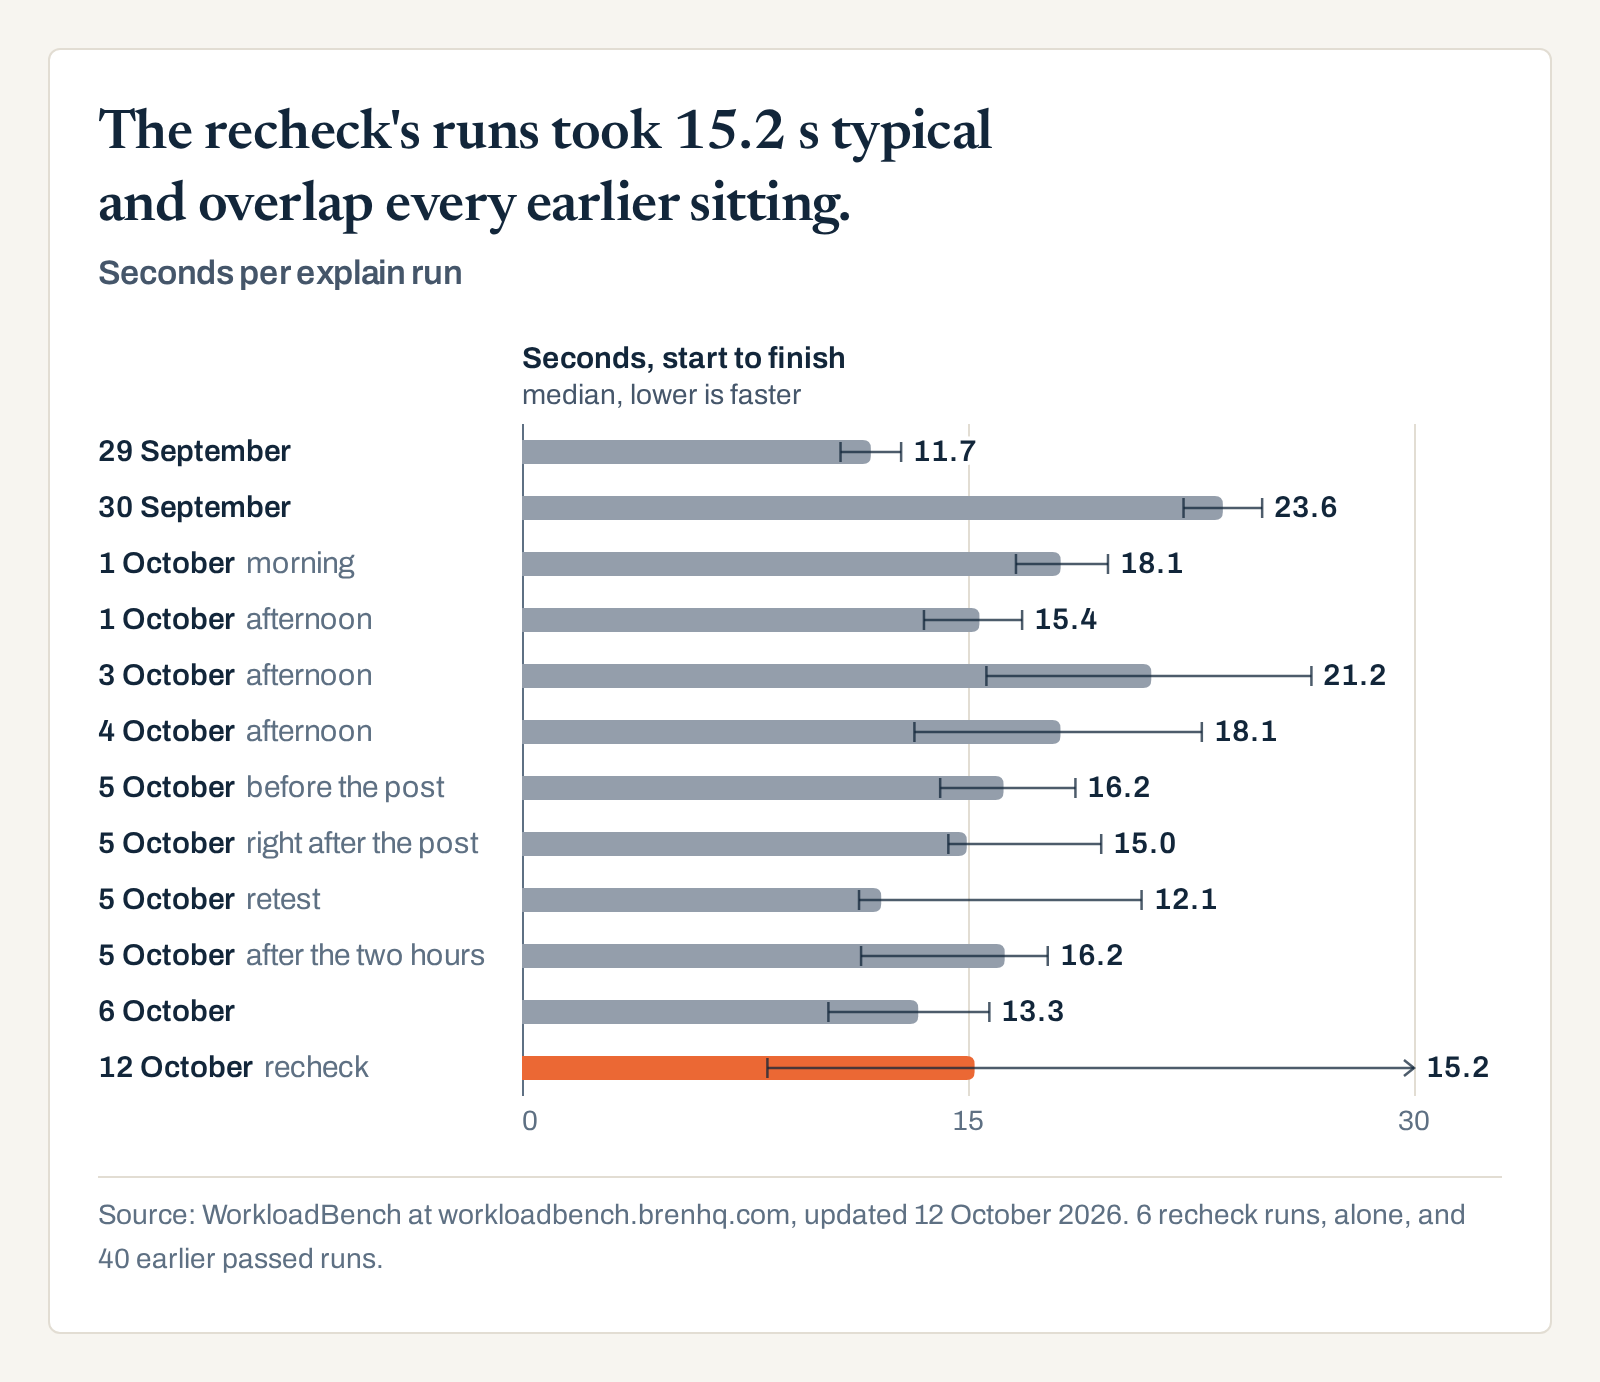
Seconds per explain run
The recheck's runs took 15.2 s typical and overlap every earlier sitting.
Source: WorkloadBench at workloadbench.brenhq.com, updated 12 October 2026. 6 recheck runs, alone, and 40 earlier passed runs.
Notes
The explain task, start to finish: the tool reads a small file and explains it. Each sitting is compared on its own; days and times of day differ.
Passed runs only. The recheck's runs ran one after another with nothing else on the machine.
The slowest recheck run took 181.5 s, 167.3 s of it waiting for the first token.
Six long-answer runs were timed that day, but their answers were not saved, so there is no TPS to compare.
GPT-6.1 Sol's explain-task speed, timed in eleven sittings, launch day included, is on its own page.
How I ran it#
Background and method
Posts on X in the week of 12 October 2026 said GPT-6.1 Sol's work had gotten better. I ran the same tests again the same way: Codex CLI 0.159.0, the same effort setting, the account's extras off, in the bench's Docker container on my own subscription. Every run is counted.
The baseline is this model's published runs from before the recheck. The bench image was rebuilt between the two rounds; the deep suite's images are frozen. Three of the four small tasks also changed setup, as the small-task notes say.
Which model answered each run is read from Claude Code's own usage report, so that check covers Claude runs only and has nothing for this one.
Limits: three runs a side on each small task and real-app test; the correctness tests were already at their ceiling, so they can show a drop but not a gain; the days and times of day differ. A recheck shows whether this model's work on these tasks changed, on this account and this CLI release. It can't show why, or how the model is trained or served.